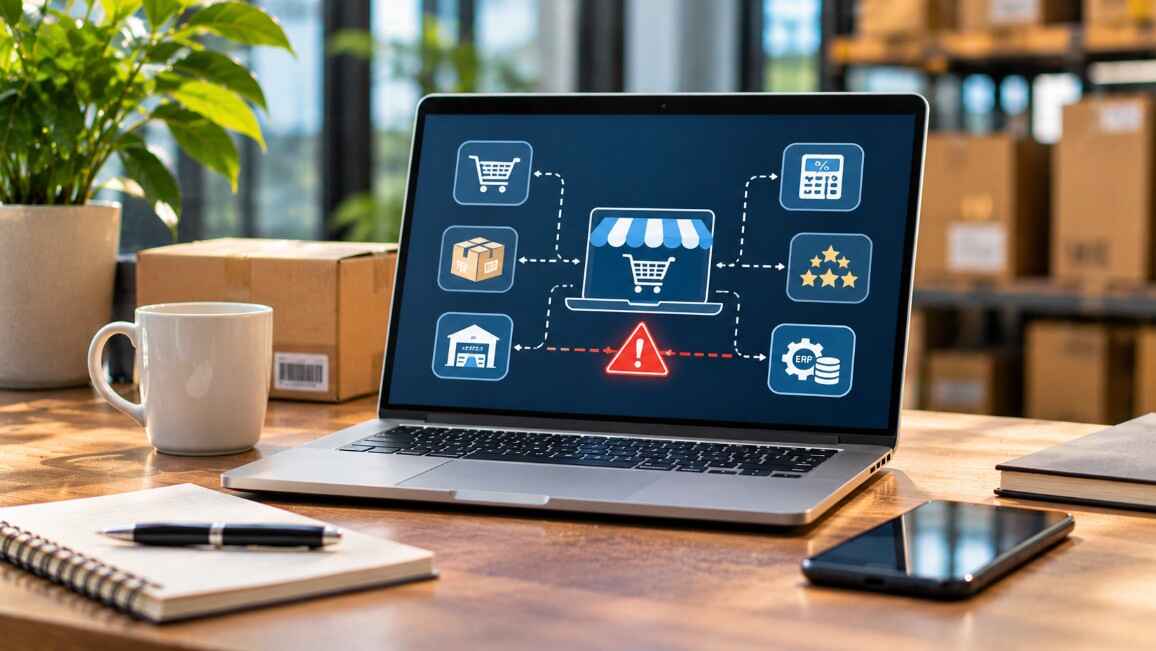
When an eCommerce integration breaks, the fix belongs to whoever has operational control of the failing component – not whoever’s logo is on the invoice. In practice, ownership splits between the storefront platform, the connector or app vendor, and the merchant’s internal or external development team. Whether recovery is quick or stretches into a prolonged outage usually comes down to clarity about where one party’s duty ends and the next begins.
The hidden cost of unclear eCommerce integration support
Most merchants only notice gaps in their eCommerce integration support the day an order fails to post to the warehouse. Until that moment, the integration diagram looks tidy: Shopify or Magento on one side; a tax engine, a 3PL, a loyalty app, and an ERP on the other. Each vendor publishes a status page, a support email, and a brochure that mentions 99.9% uptime. Nobody has a line item that says, “we fix it when the sync drifts.”
Merchants with custom integrations may use offshore software development services when their internal team lacks the capacity to maintain those connections. Digis provides custom software development and staff augmentation, including work for eCommerce businesses. Support coverage, escalation duties and access permissions should be agreed separately.
The point isn’t the uptime number printed on the brochure. It’s what happens during the 0.1%.
Why eCommerce integration failures rarely have obvious owners
Each layer in an eCommerce stack logs the error it sees, not the error it caused. A rate-limit response such as HTTP 429 from the Klaviyo API tells you only that a client exceeded a limit at that moment; Klaviyo’s rate-limit documentation asks clients to respect the Retry-After header rather than retry blindly. On its own, that response does not prove anything downstream broke or that a user transaction was affected.
That gap – between a logged symptom and an actual root cause – is where ownership arguments often start. Each vendor’s support team can honestly say their component behaved as documented, while the customer-facing issue continues elsewhere in the chain. The vendor whose logs show the first error is rarely the vendor who actually caused it.
This is why “integration ownership” shows up as a defined term in some SaaS contracts – and why so many contracts still leave it undefined.
Mapping ownership across third-party app integrations
A short responsibility matrix saves hours of finger-pointing during an incident. The table below is a starting point – adapt it to your contracts, not the other way around.
| Layer | Typical owner | What breaks here | Who usually fixes it |
| Platform API | Platform vendor | Rate limits, schema changes, deprecated endpoints | Platform + app developer |
| Connector / middleware | Vendor or internal team | Mapping drift, retry logic, expired auth tokens | Middleware owner |
| Third-party app | App developer | Webhook failures, UI bugs, data mismatches | App support team |
| Custom code (themes, scripts) | Merchant or agency | Checkout JavaScript errors, race conditions | Merchant’s dev team |
| Data contracts | Merchant | SKU mismatches, tax codes, currency rounding | Merchant + analyst |
Any unassigned layer needs an explicit owner before the integration goes live.
The fix workflow – from alert to resolution
When the alert fires, sequence matters more than speed. A disciplined response looks like this:
- Capture the exact failure signature – timestamp, request ID, payload, and HTTP status. Without these, every vendor will ask for them in turn, and the outage lasts for every one of those cycles.
- Share sanitized logs and sample requests with the vendor’s support team – PII, tokens and other secrets stripped before anything leaves your environment.
- Isolate the layer – replay the failing call in a staging environment to confirm which component actually broke.
- Open a ticket with the layer owner – include the signature, your platform version, and a reproduction path.
- Apply a temporary mitigation – a feature flag, a manual retry, or a queue pause – to limit customer impact while the root cause is investigated.
- Before reprocessing any affected traffic, confirm the operation has not already completed downstream and that your handlers are idempotent. Shopify explicitly recommends idempotent webhook handling for exactly this reason.
- Reconcile orders, inventory and statuses across each integrated system before closing the incident – a restored webhook does not retroactively repair records written incorrectly during the outage.
- Write the post-mortem – what broke, who fixed it, what will change in monitoring and alerting. Share it across teams and vendors.
The ticket you can’t write is the ticket nobody can answer.
Building a sustainable eCommerce integration maintenance plan
A one-time fix is cheap. A maintenance posture is what protects revenue through the next platform update. The elements worth putting in writing:
- A named owner per integration, plus a backup contact for when that person is on leave.
- Quarterly review of API versions in use – platforms like Shopify and BigCommerce deprecate endpoints on predictable cycles, and surprise should never be the reason you learn about one.
- Health checks that exercise the full order path – with scoped payment credentials, controlled fulfillment, and automatic cleanup of test records. Running unconditional test purchases against live production without those safeguards creates its own incident.
- Alerting that distinguishes between “slow” and “broken” – they need very different responses.
- A shared changelog between the merchant, the app vendors, and any external developers. Order synchronization issues often trace back to a quiet change nobody flagged.
An integration you don’t monitor is an integration that fails silently.
Merchants who stay calm during incidents are rarely the ones with the biggest teams. They’re the ones who decided, before anything broke, who gets paged.
Assigning ownership before the next integration failure
The honest answer to the opening question: when an eCommerce integration breaks, the fix is owned by whoever defined its boundaries in writing. If nobody did, the merchant usually absorbs it – because the merchant is the party whose revenue stops when the integration stops.
Treat every third-party app integration as a shared responsibility that must be assigned, not assumed. Draft the responsibility matrix before the contract is signed, and agree escalation paths, access permissions and monitoring coverage alongside it. A named owner with no log access, no deploy permissions and no view of alerts is not really the owner.
When the matrix has a gap – an endpoint nobody will claim – decide early whether to fund it internally, bring in a specialist partner, or renegotiate scope with the vendor who introduced it. Clear ownership lives at the intersection of the contract, the architecture, the access permissions, the monitoring and the team’s actual ability to fix what breaks – not in the contract alone.
Leave a Reply